RAG in the Enterprise: What It Is
RAG (retrieval-augmented generation) is the technique that allows an AI to answer by relying on your internal documents, rather than on its general knowledge alone. It is what makes the difference between an AI that invents a plausible answer and an AI that relies on your real data. At Unibail-Rodamco-Westfield (URW), a commercial real estate group with 4,200 employees, this approach allowed non-technical teams to query their Snowflake data directly in natural language, without writing a single line of SQL. Here is how RAG works in practice, why it matters for a company, its use cases and the points to watch before deploying it.
What RAG is in practice
A language model on its own answers from what it learned during training, without knowing your internal data. It knows nothing about your procedures, your contracts or last week's figures. When it does not know, it tends to produce an answer that is plausible but wrong.
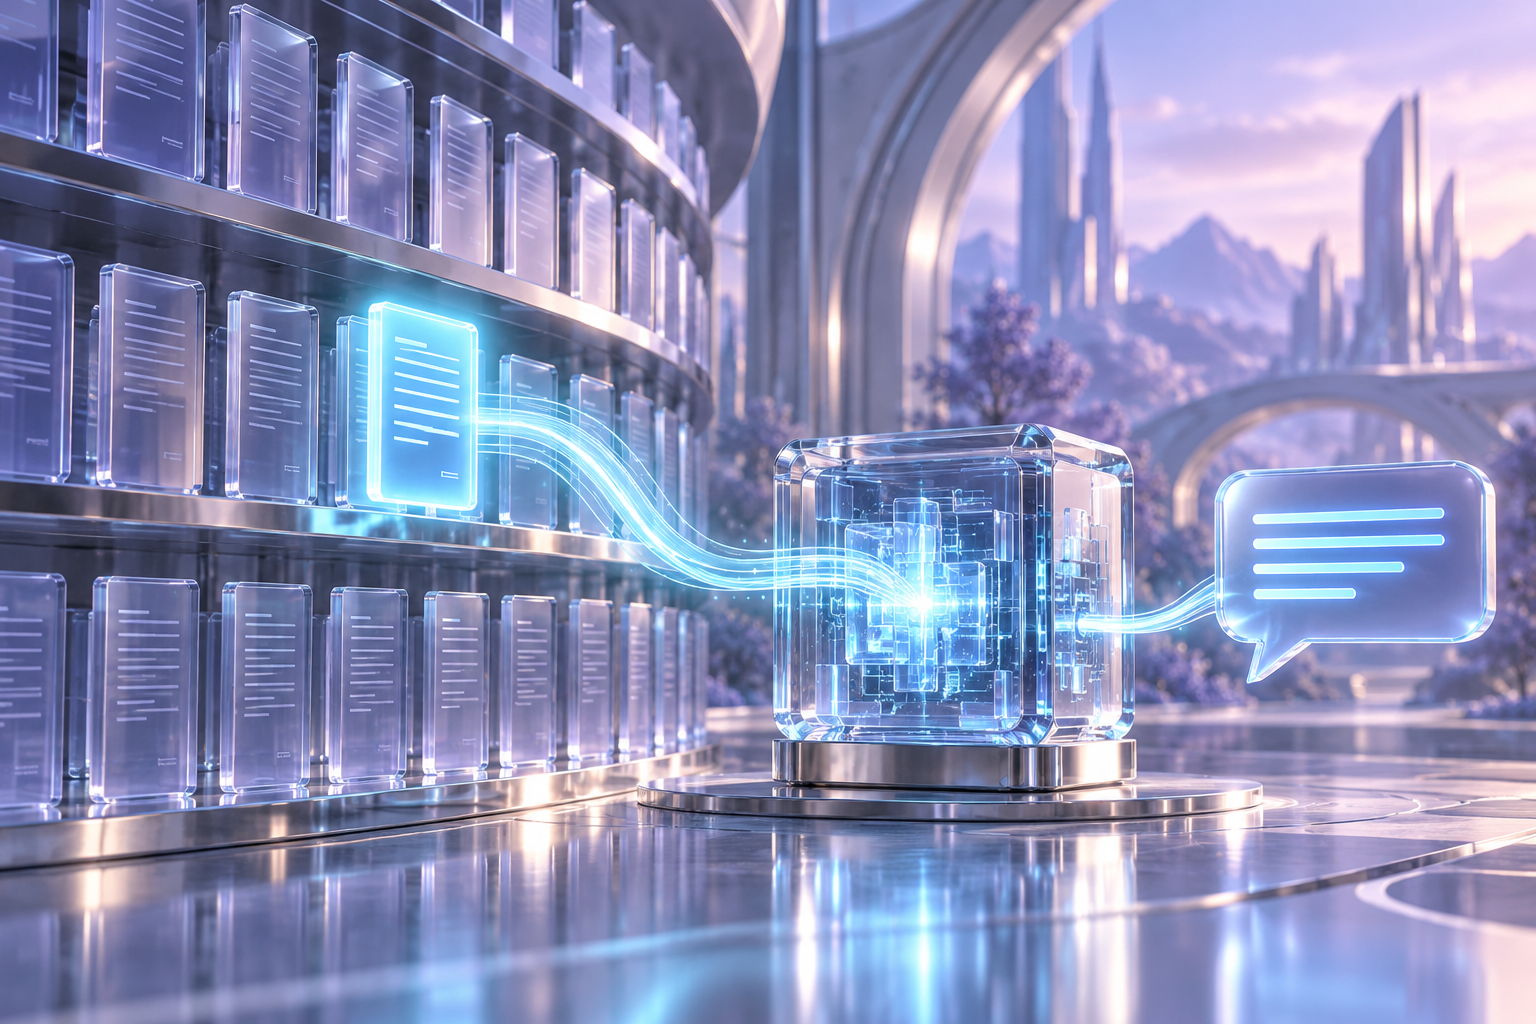
RAG adds a step before the answer is generated: the system first looks for the relevant passages or data in your sources, then provides them to the AI so that it builds its answer from these precise elements, rather than inventing a generic answer. You can compare it to a colleague who, before answering, opens the right file instead of answering from memory.
The three steps of a RAG system
A RAG system works in three stages. First, indexing: your documents or tables are split and organized so that they can be found quickly by meaning, not only by exact words. Next, retrieval: for each question, the system finds the passages closest to the request. Finally, generation: the AI writes an answer from these passages and can cite its sources. The quality of the result depends on all three, but it is almost always indexing, and therefore data preparation, that makes the difference.
The URW case: making Snowflake accessible without technical skills
All of URW's data is hosted in Snowflake, but in practice it remained inaccessible to most employees. Getting a simple answer such as “Which of our centers had the most visitors this quarter?” meant either mastering SQL or asking the Data teams, creating a bottleneck that slowed decision-making at every level.
Qolaig designed and deployed a Natural Language to SQL system: a conversational interface that turns a question asked in natural language into an SQL query executed directly on Snowflake, then returns the answer in a clear and understandable way.
The main difficulty of the project was not technical, it was semantic. Every company has its own vocabulary, its in-house indicators, its internal synonyms. Qolaig built a custom business glossary for URW, allowing the AI to understand the exact definitions of the indicators and the calculation rules specific to the group. It is this layer that guarantees the relevance and reliability of the generated queries, which is exactly the RAG principle applied to a structured database rather than to text documents.
Results: natural language access to data for all business teams, a reduced load on the Data teams for routine queries, and faster decision-making thanks to the removal of intermediation delays. The full case study details how the glossary and the query layer were built step by step.
Why it matters for a company
Reducing hallucinations. An AI that relies on your real documents or data rather than on its general knowledge invents far less false information. It can also indicate where its answer comes from, which makes it possible to check it.
Keeping information up to date. Unlike a model trained at a given moment, a RAG base can be updated continuously: you add a document and it is taken into account immediately, without retraining anything.
Using confidential data without exposing it. RAG allows the AI to rely on sensitive internal documents or databases without this data being used to train an external model. Our article on agentic AI governance and security details the access rules to plan for.
RAG, fine-tuning or a long context window: how to choose
There are three approaches to giving an AI knowledge of your company. Fine-tuning modifies the model itself: it is expensive, has to be redone with every change, and is mainly useful for changing a style or a skill. Pasting all your documents into the request works for a small volume, but becomes slow, expensive and unreliable as soon as the documentation grows. RAG retrieves only the passages useful for each question: it is the most flexible approach when information changes often and the volume is large. For most business cases, RAG is the right starting point.
Concrete RAG use cases in the enterprise
An agent connected to a structured database, as at URW, to query business indicators in natural language and get an answer without going through the Data teams.
An internal support assistant that answers employees' questions based on HR procedures or product documentation, like the chatbot deployed at Dana Avocats, described in our article on the enterprise chatbot.
A document search tool that makes it possible to quickly find a precise piece of information in thousands of pages: contracts, technical manuals, meeting reports.
A business copilot that relies on the catalog or the customer base to prepare personalized answers, as in our article on the AI copilot in the enterprise.
The points to watch before deploying RAG
The quality of the source. A RAG system only finds and cites what exists. Outdated, contradictory or poorly written documents will produce answers of the same level. At URW, most of the work lay in building the business glossary, not in the technical connection to Snowflake alone.
The right segmentation of data. The way documents or tables are structured before being queried directly influences the relevance of the answers. A document split without logic brings up passages out of context.
Access rights. If the AI has access to all documents, it can answer an employee with information they are not allowed to see. The existing rights must be reproduced in the system.
Monitoring over time. The questions without a satisfactory answer reveal the gaps in the document base. Tracking them makes it possible to improve the system gradually.
According to the KPMG AI Pulse 2026 study, the quality and updating of data remain a poorly clarified area of responsibility in a majority of French organizations, a point directly linked to the reliability of any RAG architecture.
FAQ
Is RAG reserved for large companies?
No. As soon as a company has a document base or structured data, even a modest one, RAG can be set up at an appropriate scale. The URW case shows the implementation on a complex case, but the same principles apply to a few hundred documents.
What is the difference between RAG and fine-tuning a model?
Fine-tuning modifies the model itself based on your data, which is expensive and must be redone with every update. RAG leaves the model unchanged and retrieves the information for each question, which makes it much simpler to keep up to date, like URW's business glossary, which can be updated without touching the model. It often relies on the Model Context Protocol (MCP) to connect to the sources.
At Qolaig, our Workshop → Build → Run methodology frames this type of project before any technical investment. Let's talk about your project.
Our latest articles
Tesla Flying Car: What the Roadster Demo Means for AI
Prompt Engineering: How to Talk to AI Effectively